Introduction – What Is Proteomics?
Proteomics is the large-scale study of proteins present in a cell, tissue, organism, or biological system under a particular set of conditions. While genomics describes the genetic information available to an organism and transcriptomics examines which genes are being transcribed into RNA, proteomics moves closer to the molecular machinery carrying out many cellular functions.
A proteome is dynamic. Protein abundance can change with growth conditions, stress, disease, environmental exposure, developmental stage, or treatment. Proteins can also be cleaved, modified after translation, transported to different cellular locations, or assembled into complexes.
Proteomics therefore allows researchers to investigate not only which proteins are detected, but also how their abundance varies between samples and, with appropriate experimental approaches, their post-translational modifications, interactions, or localization.
Mass spectrometry is the dominant technology in modern proteomics, supported by increasingly sophisticated computational methods for protein identification, quantification, statistical analysis, and biological interpretation.
A Brief History of Proteomics
The term proteomics emerged in the 1990s alongside the rapid expansion of genomics. Early large-scale protein studies relied heavily on two-dimensional gel electrophoresis (2-DE), which separates proteins according to properties such as charge and molecular mass before identification.
The field changed substantially with the development of liquid chromatography coupled to tandem mass spectrometry (LC-MS/MS). High-resolution mass spectrometers can now generate large datasets containing information from thousands of peptides across complex biological samples.
Modern proteomics extends well beyond protein identification. Depending on the experimental design, researchers can quantify protein abundance, characterize post-translational modifications (PTMs) such as phosphorylation or acetylation, investigate protein complexes, and study how proteomes respond to biological or environmental changes.
Common Proteomics Workflows
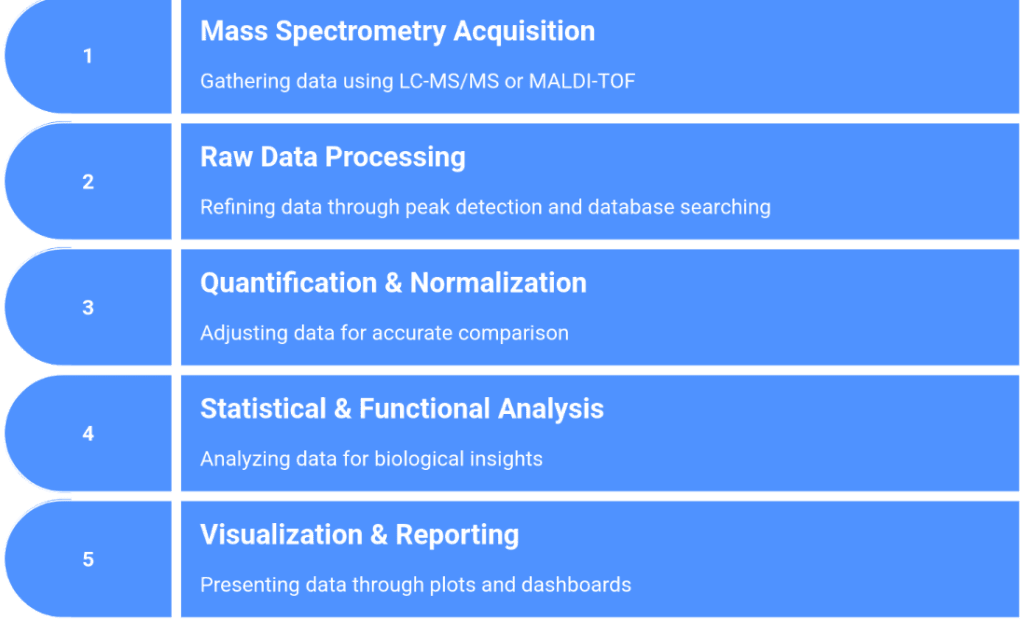
Although experimental designs vary considerably, a typical mass-spectrometry-based proteomics workflow moves through several broad stages.
1. Sample Preparation
Proteins first need to be extracted from the biological material and prepared for mass spectrometry.
In bottom-up proteomics, proteins are usually enzymatically digested into peptides, commonly using trypsin. Depending on the sample and experimental objectives, preparation may also include protein or peptide fractionation, cleanup, depletion of highly abundant proteins, or enrichment for particular classes of modified peptides.
Different preparation strategies are available, including in-solution digestion and methods such as S-Trap, SP3, or FASP. The most appropriate approach depends on the sample type, laboratory workflow, and downstream analytical objectives.
2. LC-MS/MS Data Acquisition
In a typical LC-MS/MS experiment, peptides are first separated using liquid chromatography and then introduced into a mass spectrometer.
The instrument measures peptide ions and fragments selected ions to generate tandem mass spectra that can be used for peptide identification.
Two common acquisition strategies are:
- Data-dependent acquisition (DDA): the instrument selects precursor ions for fragmentation based on signals detected during the run.
- Data-independent acquisition (DIA): broader mass-to-charge windows are systematically fragmented, generating more comprehensive but computationally complex datasets.
Targeted approaches such as parallel reaction monitoring (PRM) or selected/multiple reaction monitoring (SRM/MRM) can instead focus on predefined peptides or proteins.
3. Peptide and Protein Identification
Raw mass spectrometry files must be computationally processed before biological interpretation.
Software such as MaxQuant, Proteome Discoverer, Mascot, and FragPipe can match experimental spectra against predicted peptide spectra derived from protein sequence databases.
These workflows normally include several layers of quality control, including peptide-spectrum matching, false discovery rate (FDR) control, peptide assignment, and protein inference.
Protein inference is an important consideration because some peptide sequences occur in multiple proteins. Consequently, converting peptide-level evidence into confident protein-level identifications is not always a simple one-to-one process.
4. Protein Quantification
Once peptides and proteins have been identified, their abundance can be estimated using different experimental strategies.
Label-free quantification (LFQ) compares peptide or protein signals across independently measured samples. It is flexible and widely used, particularly when many samples need to be analyzed without chemical or metabolic labeling.
Isobaric labeling, including approaches such as TMT or iTRAQ, allows several samples to be combined and analyzed together. Relative abundance is then estimated using reporter ions generated during tandem mass spectrometry.
Metabolic labeling, such as SILAC, introduces stable isotope-labelled amino acids during cell growth and can provide highly controlled relative quantification in compatible experimental systems.
The appropriate quantification strategy depends on the biological system, number of samples, available instrumentation, experimental design, and analytical goals.
5. Statistical and Functional Analysis
Protein quantification produces abundance data that must then be interpreted in the context of the experimental design.
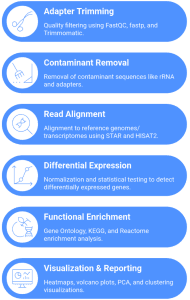
- quality control and assessment of sample structure;
- normalization and filtering;
- identification of differentially abundant proteins between conditions;
- clustering, PCA, heatmaps, and other exploratory analyses;
- functional annotation and enrichment analysis;
- pathway analysis using resources such as KEGG, Reactome, and Gene Ontology;
- integration with transcriptomic, genomic, or other molecular data where appropriate.
The objective is not simply to produce a list of proteins, but to connect quantitative changes with the biological question behind the experiment.
What Does Proteomics Data Actually Look Like?
The answer depends on where you enter the analysis workflow.
At the instrument level, a proteomics experiment may generate vendor-specific raw mass spectrometry files or open formats such as mzML. After peptide identification and quantification, researchers often work with tables containing peptide-spectrum matches, peptide identifications, protein groups, abundance values, and quality metrics.
For downstream biological analysis, one of the most useful inputs is usually a protein or peptide abundance matrix: rows represent proteins or peptides, columns represent samples, and the values represent measured or normalized abundance.
This matrix must be combined with accurate sample metadata describing experimental groups, biological replicates, treatments, time points, batches, or other variables.
At this stage, questions that initially appear simple — Which proteins changed? Which pathways are affected? Are the replicates consistent? — become statistical and bioinformatic problems.
Label-Free vs Label-Based Proteomics
There is no universally superior quantification strategy. Each approach involves trade-offs.
Label-Free Quantification
Label-free workflows do not require isotopic or isobaric labelling of samples.
Advantages include relatively straightforward sample preparation, flexibility in the number of samples, and good scalability for larger studies.
Because samples are generally measured separately, however, technical variation between LC-MS runs must be considered carefully during quality control, normalization, and statistical analysis.
Isobaric Labeling: TMT and iTRAQ
TMT and iTRAQ use chemical labels that allow multiple samples to be combined into a multiplexed experiment.
This can improve throughput and reduce some forms of run-to-run variation, but the workflow requires additional sample preparation and careful experimental design. Quantitative accuracy can also be affected by phenomena such as ratio compression, depending on the acquisition strategy.
The number of samples that can be multiplexed depends on the labeling chemistry and analytical setup, so it is better considered a property of the specific experiment rather than a fixed characteristic of “label-based proteomics.”
SILAC and Other Metabolic Labels
SILAC introduces stable isotope-labelled amino acids while cells are growing. Because labelled and unlabelled samples can be combined early in the workflow, SILAC provides strong internal quantitative control.
Its use is nevertheless restricted to biological systems that can incorporate the labelled amino acids under controlled growth conditions.
The choice between LFQ, isobaric labeling, metabolic labeling, or targeted proteomics should therefore follow the biological question and experimental constraints rather than a simple “best method” hierarchy.
Why Proteomics Complements Genomics and Transcriptomics
Genomics, transcriptomics, and proteomics measure different layers of biological information.
DNA describes genetic potential. RNA abundance provides information about transcriptional responses. Protein measurements provide information about the abundance of many of the molecules that execute or regulate cellular processes.
These layers are related, but they are not equivalent.
Changes in mRNA abundance are not always accompanied by proportional changes in protein abundance. Translation rates, protein degradation, post-translational modifications, localization, and regulatory interactions can all alter the relationship between transcript and protein levels.
Proteomics can therefore complement transcriptomics by showing whether transcriptional changes are reflected at the protein level and by revealing regulatory effects that cannot be inferred reliably from RNA abundance alone.
Specialized proteomics experiments can also investigate PTMs such as phosphorylation, acetylation, or ubiquitination, providing another regulatory layer beyond total protein abundance.
For an example of how transcriptomic and proteomic information can be combined in microbial research, see our published study on transcriptomic and proteomic responses associated with feather keratin degradation by Fervidobacterium.
Microbial and Environmental Proteomics
Proteomics is particularly valuable in microbiology because microbial cells can alter their protein profiles rapidly in response to nutrient availability, temperature, stress, antimicrobials, host interactions, or other environmental factors.
In microbial communities, metaproteomics extends this concept by examining proteins recovered from complex samples containing multiple organisms.
Where metagenomics describes the genes and genomes present in a microbial community, metaproteomics provides direct evidence for proteins expressed within that community.
This can help researchers investigate functions such as nutrient utilization, carbon cycling, stress responses, antimicrobial resistance mechanisms, or host–microbe interactions.
Interpretation can nevertheless be challenging. Peptides may be shared between related organisms, reference databases can be incomplete, and assigning proteins confidently to particular taxa may not always be possible.
For microbiome studies, proteomic information can therefore complement community composition and genomic potential rather than replace them. If your main question concerns taxonomic composition from marker-gene sequencing, see our microbiome data analysis services.
Applications of Proteomics
Proteomics is now used across a broad range of biological disciplines.
- Biomedical research: proteomic data can be used to study disease mechanisms, discover candidate biomarkers, and characterize responses to treatment.
- Drug discovery: proteomics can help investigate potential therapeutic targets, drug mechanisms, and resistance pathways.
- Microbial proteomics: protein-level measurements can reveal metabolism, stress adaptation, virulence, secretion, and interactions between microorganisms and their environment.
- Environmental proteomics and metaproteomics: these approaches can reveal protein-level responses and functions within complex ecosystems.
- Agricultural proteomics: proteomic approaches are used to investigate plant stress, crop physiology, pathogen responses, and other processes relevant to food and agricultural research.
The specific analytical workflow varies considerably between these applications, but the general objective is the same: convert complex protein measurements into interpretable biological evidence.
Multi-Omics Integration
No single omics layer captures an entire biological system.
Combining proteomics with transcriptomics, genomics, or metagenomics can help researchers distinguish between genetic potential, transcriptional regulation, and protein-level responses.
For example, genes that change strongly at the RNA level but not at the protein level may point toward post-transcriptional regulation. Conversely, protein-level changes without corresponding differences in RNA abundance can highlight differences in translation, degradation, or protein stability.
Multi-omics analysis is therefore most useful when the individual datasets are interpreted together around a specific biological question rather than simply combined because several data types are available.
From Proteomics Data to Biological Interpretation
Generating mass spectrometry data is only the beginning of a proteomics project.
Once spectra have been converted into protein or peptide measurements, researchers still need to assess data quality, define valid comparisons, normalize abundance data, select appropriate statistical methods, control false discoveries, annotate proteins, investigate pathways, and interpret the results in the context of the experiment.
These downstream steps determine whether a proteomics dataset becomes an interpretable biological result or remains a collection of abundance tables.
If you are preparing a proteomics study for publication, data deposition is another important step. Our practical guide explains how to submit proteomics data to PRIDE, from organizing files and metadata to preparing the submission.
How Tailoredomics Supports Proteomics Projects
Proteomics data analysis at Tailoredomics focuses on turning existing mass spectrometry data or processed proteomics outputs into interpretable, documented results.
Depending on the starting data and research question, a project can include input and metadata review, quality assessment, peptide- or protein-level data processing, normalization, statistical comparisons, differential abundance analysis, functional annotation, pathway enrichment, visualization, and biological interpretation.
Raw mass spectrometry processing can also be considered when the instrument files, experimental design, and required workflow are compatible with the agreed project scope. Sample preparation and mass spectrometry acquisition themselves are performed externally.
For studies combining several molecular layers, proteomics results can also be interpreted alongside transcriptomic, genomic, or microbial community data where scientifically appropriate.
Deliverables can include processed and annotated tables, publication-ready figures, documented methods, and a structured summary of the analysis and main findings.
The analytical workflow is defined around the dataset and biological question rather than forcing every project through the same fixed pipeline.
Already have proteomics data and need help with the analysis? Explore our proteomics data analysis services or tell us about your project.